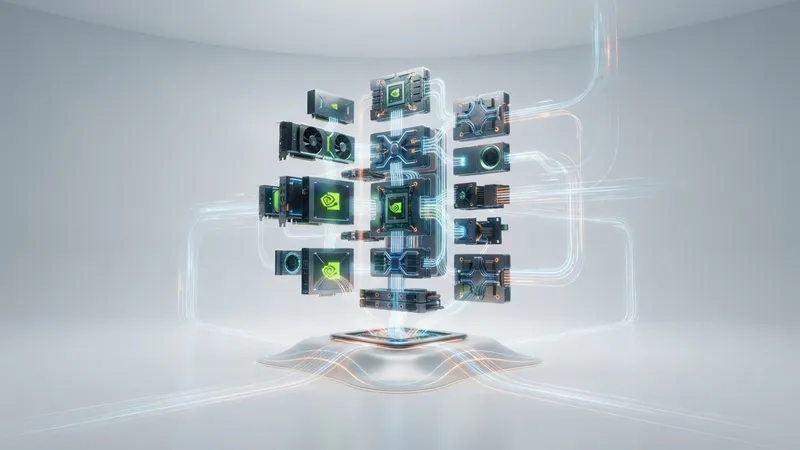
The economics of an artificial intelligence factory are increasingly dependent on more than just access to high-performance graphics processing units (GPUs). As agentic systems draw on multiple models, databases, and tools, the entire data center must function as a single, cohesive computing system.
This transition is shifting attention from individual chips to the broader infrastructure that translates computing capacity into useful intelligence. According to Ian Buck, vice president and general manager of hyperscale and HPC at Nvidia Corp., networking, storage, processors, and software must operate together at scale while maximizing the output generated from every unit of power.
Buck emphasized, “Instead of cars or devices or PCs, it’s tokens. These assets are not IT; they’re not cost. They’re actually appreciating, revenue-generating, fungible, durable, productive parts of an economy.”
The commercial output of an AI factory primarily stems from inference, where deployed models process requests and produce #tokens. However, #inference does not supersede training, as organizations continually update deployed models in response to changing data and market conditions. Buck noted, “It’s not just fire and forget on all these services. As companies are using these models, they’re refining them, aligning them, and adding more data to them. Keeping them up to date and aware—that actually involves a bit of training. We’re seeing work in reinforcement learning and online alignment.”
Low latency establishes another economic tier for workloads where faster reasoning yields greater value. Nvidia’s Groq 3 LPX inference accelerator, when paired with its Vera Rubin platform, boosts per-user token rates for time-sensitive applications, particularly in sectors like fintech.
Power capacity ultimately caps the amount of computing infrastructure a data center can deploy. This constraint makes “tokens per watt” a central metric for AI factory economics, pushing vendors to enhance performance with each hardware generation. #Nvidia ensures that the tokens per watt efficiency of its GPUs improves by upwards of 10 times with every generation, culminating in a remarkable 30x improvement with the Blackwell architecture.
[AgentUpdate Depth Analysis] The evolution of AI Agents, particularly those powered by Large Language Models (LLMs), increasingly demands a holistic view of computational resources. Nvidia's emphasis on token economics and power efficiency directly addresses critical bottlenecks in scalable agent deployment. Unlike traditional software, an agent's true value isn't just in its output quality but also in its efficiency, measured by tokens per watt. This shifts the focus for developers utilizing frameworks like LangChain or CrewAI from merely orchestrating tasks to deeply optimizing the underlying computational cost of those orchestrations. Future agent designs will prioritize leaner execution paths, intelligent tool invocation, and efficient memory management to maximize token output within defined power envelopes. This focus will drive innovation in agent architecture and system design, leading to more resource-aware and economically viable AI Agent systems, ultimately accelerating their integration into real-world applications by making their operation more sustainable and cost-effective across the entire AI ecosystem.